 WhatsApp Us Now
Modern businesses generate enormous volumes of information through websites, mobile applications, customer transactions, enterprise software, connected devices and digital services. However, collecting data is only the beginning. Organisations need to ensure that information is accurate, consistent, accessible and ready for analysis before using it to make business decisions.
Poor-quality data can affect everything from financial reporting and customer segmentation to demand forecasting and automated decision-making. Even advanced analytics platforms cannot produce dependable results when the information entering them is incomplete, outdated or incorrectly structured. This makes data quality and pipeline reliability two essential priorities for organisations building modern data infrastructure.
Understanding the Importance of Data Quality
Data quality refers to how accurately and consistently information represents the real-world activity it is intended to describe. High-quality data should be complete, valid, consistent, timely and free from unnecessary duplication.
Consider an e-commerce business managing thousands of customer transactions every day. If customer records contain duplicate entries, product prices are incorrectly stored or transaction dates are inconsistent, the organisation may generate inaccurate sales reports. These errors can influence inventory planning, marketing decisions and revenue forecasts.
The same challenge applies to financial institutions, healthcare organisations, logistics companies and technology businesses. Each relies on dependable information to manage operations and make informed decisions.
Maintaining data quality therefore requires more than occasional spreadsheet checks. Businesses need structured validation processes, appropriate storage systems, monitoring mechanisms and reliable data pipelines.
How Data Pipelines Support Business Operations
A data pipeline is a structured process that moves information from its original source to a destination where it can be stored, transformed and analysed. These sources may include databases, APIs, business applications, transaction systems and cloud storage platforms.
A typical pipeline involves three important stages: data ingestion, transformation and loading. During ingestion, information is collected from different sources. Transformation prepares it for further use by cleaning records, standardising formats, removing duplicates and applying business rules. Finally, the processed information is loaded into a suitable destination, such as a data warehouse or analytics platform.
The reliability of each stage affects the quality of the final output. A pipeline that fails to process new transactions or introduces duplicate records can create reporting inconsistencies. Businesses therefore need systems that can detect errors, manage failed processes and maintain consistent data flows.
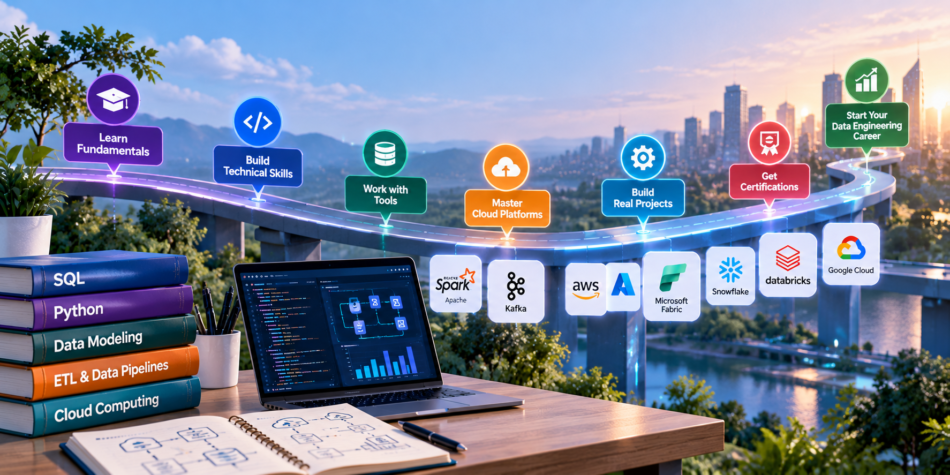
Professionals entering this field need a strong understanding of databases, SQL, Python, ETL processes and data modelling. A structured data engineer course can help learners develop the foundational knowledge required to understand how information moves through modern data environments.
Common Causes of Poor Data Quality
Data quality problems often develop because organisations collect information from multiple systems that were not originally designed to work together.
One common issue is inconsistent data formats. Different applications may store dates, currencies, addresses and customer identifiers in different formats. Without standardisation, combining this information becomes difficult.
Duplicate records are another major challenge. The same customer or transaction may appear multiple times because information is entered through different channels. These duplicates can distort business reports and create confusion across departments.
Incomplete information can also affect decision-making. Missing customer details, transaction values or product attributes may prevent analysts from generating accurate insights. In addition, outdated information can lead to decisions based on business conditions that no longer exist.
Manual data processing introduces further risks. Repeated spreadsheet operations and disconnected workflows increase the possibility of human error. Automating validation and transformation processes can reduce these problems and improve consistency.
The Role of Cloud Platforms in Reliable Data Management
As organisations expand their digital operations, managing data through isolated systems becomes increasingly difficult. Cloud platforms provide infrastructure and services that help businesses collect, process, store and analyse information at scale.
Cloud-based data engineering environments support automated workflows, distributed processing and integration with multiple data sources. They also make it easier to monitor pipeline performance and adapt infrastructure as business requirements change.
Microsoft Azure provides services for data integration, processing and analytics across cloud environments. Professionals interested in developing expertise in this ecosystem can consider a dedicated Azure learning pathway to understand how cloud-based data solutions are designed and managed.
Amazon Web Services offers another extensive environment for building scalable data architectures. Its services support data ingestion, storage, transformation, orchestration and analytics. A structured aws data engineer full course can help learners understand the AWS ecosystem and the processes involved in building dependable cloud data workflows.
The choice of platform depends on an organisation’s existing technology infrastructure, data requirements, security needs and long-term business objectives.
Why Data Governance and Monitoring Matter
Reliable pipelines require continuous monitoring. A process that works correctly today may encounter problems tomorrow because of changes in source systems, unexpected data volumes or modifications to business requirements.
Data monitoring helps organisations identify these issues before they affect downstream reporting and analytics. Teams can track pipeline execution, processing delays, failed jobs and unexpected changes in data volume.
Data governance establishes the policies and responsibilities required to manage information properly. It covers access permissions, security, data ownership, retention policies and compliance requirements.
For organisations handling sensitive financial or customer information, governance is particularly important. Appropriate controls help ensure that only authorised individuals can access specific datasets while maintaining accountability across the data lifecycle.
A dependable data environment combines automated validation, monitoring, documentation and governance rather than relying on a single technology.
The Growing Importance of Microsoft Fabric in Data Engineering
Modern data environments increasingly require professionals to work across ingestion, transformation, analytics and reporting instead of managing each activity independently.
Microsoft Fabric brings several data and analytics capabilities together within a unified platform. Its environment includes tools for data engineering, data integration, data warehousing, real-time analytics and business intelligence.
For data professionals, understanding how these capabilities connect is important when designing efficient analytical workflows. They need to know how information is ingested, transformed, organised and made available for reporting.
The fabric data engineer learning pathway is relevant to professionals who want to build skills around Microsoft’s Fabric ecosystem and understand its role in modern data engineering.
How Reliable Data Supports Artificial Intelligence
Artificial intelligence systems depend heavily on the information used to train, evaluate and operate them. If the underlying data contains errors, inconsistencies or outdated information, the resulting predictions and outputs may become unreliable.
For example, a retail forecasting system may generate inaccurate demand predictions if its historical sales records contain missing transactions. Similarly, a customer service AI application may provide incorrect responses if its knowledge sources are outdated.
This relationship makes data engineering an important part of successful AI implementation. Organisations must establish dependable data sources, maintain consistent processing workflows and ensure that information remains accessible to the applications using it.
AI professionals also need to understand how these systems interact with existing business operations. A forward deployed ai engineer focuses on implementing and integrating AI solutions within real business environments, where data accessibility, system compatibility and operational reliability can directly influence project outcomes.
Building a Future-Ready Data Engineering Skill Set
The growing importance of reliable data infrastructure has increased the demand for professionals who can work with databases, cloud platforms, automation and analytical systems.
A strong technical foundation begins with SQL, Python, data modelling and ETL concepts. From there, professionals can develop expertise in cloud services, pipeline orchestration, data warehousing, monitoring and governance.
Practical experience is equally important. Working with real datasets, building transformation workflows and troubleshooting pipeline failures helps learners understand challenges that cannot be fully addressed through theoretical knowledge alone.
The ability to maintain data quality and build dependable systems is becoming valuable across industries. As businesses continue adopting cloud computing, advanced analytics and artificial intelligence, professionals who understand the complete data lifecycle will be better prepared to contribute to these initiatives.
Conclusion
Data quality and pipeline reliability are fundamental to modern business operations. Organisations need more than large volumes of information; they need dependable systems that can collect, validate, transform and deliver accurate data whenever it is required.
From cloud-based analytics to artificial intelligence, every data-driven application depends on the quality of its underlying information. Businesses that invest in reliable pipelines, continuous monitoring and strong governance can reduce operational errors and make more informed decisions.
For aspiring professionals, developing practical data engineering skills offers an opportunity to work on the infrastructure supporting modern digital businesses. Understanding how data moves, how errors are controlled and how cloud platforms support analytical workflows provides a strong foundation for long-term growth.
Frequently Asked Questions
1. Why is data quality important in data engineering?
Data quality ensures that information is accurate, complete, consistent and suitable for analysis. It helps organisations avoid reporting errors and make decisions based on dependable information.
2. What is a reliable data pipeline?
A reliable data pipeline consistently collects, processes and delivers information while handling errors, maintaining data accuracy and supporting continuous monitoring.
3. What are the main causes of poor data quality?
Common causes include duplicate records, missing information, inconsistent formats, outdated datasets, manual processing errors and disconnected business systems.
4. Which skills are important for building data pipelines?
Important skills include SQL, Python, database management, ETL processes, data modelling, cloud computing, workflow orchestration and data validation.
5. How does cloud computing improve data management?
Cloud platforms provide scalable infrastructure and integrated services for data ingestion, processing, storage and analytics. They also support automation and monitoring across data workflows.
6. How does data quality affect artificial intelligence?
AI systems rely on accurate and relevant information. Poor-quality data can lead to unreliable predictions, incorrect outputs and inconsistent application performance.
7. What is the difference between data engineering and data analytics?
Data engineering focuses on building and maintaining the systems that collect, process and organise information. Data analytics uses that prepared information to identify patterns, generate insights and support business decisions.


